The website accepts an order, the customer receives a confirmation, and the warehouse never sees it. Or a trade buyer signs in to find yesterday’s price while the sales team insists the ERP is correct. These are operational failures that can affect revenue, margin and customer confidence even when the storefront appears healthy.
For Australian and New Zealand retailers, wholesalers and distributors, the immediate question is usually practical: what has failed, which transactions are affected, and how do we recover without creating another problem?
OSE’s recommended starting point is to follow the business transaction across every system, establish the last confirmed outcome, and recover only the records that need intervention. A successful connection or a green dashboard does not prove that an order is ready for fulfilment.
This guide focuses on operating and repairing an existing integration. For the broader architecture and planning decisions, see our ERP integration guide for B2B eCommerce.
Key Takeaways
- Trace failed transactions across the store, integration and ERP before replaying them.
- Correct data and mapping faults; reserve bounded retries for appropriate temporary failures.
- Reconcile destination outcomes and prevent duplicate business actions during recovery.
- Assign owners and monitor unresolved work against operational deadlines.
Start by containing the business impact
Appoint one incident owner who can coordinate the commerce, integration, ERP and warehouse teams. Record when the issue began, the affected channels and what customers are experiencing. Preserve logs and identify the most recent relevant release or configuration change before evidence is overwritten.
Then decide which operations can continue safely. A delayed order transfer may allow checkout to continue if orders are stored durably and the business can meet its fulfilment promises. Incorrect contract prices or unreliable stock may require affected products, accounts or ordering routes to be restricted while the issue is investigated.
Make this a commercial decision with the relevant operational owners. Do not automatically disable the entire store, or leave everything available because the homepage loads. Give customer service a clear explanation, an approved workaround and a time for the next update.
Keep a single list of affected transactions. Record manual interventions against the original order reference so later recovery does not create a second order or trigger a second shipment.
Trace one failed transaction from checkout to fulfilment
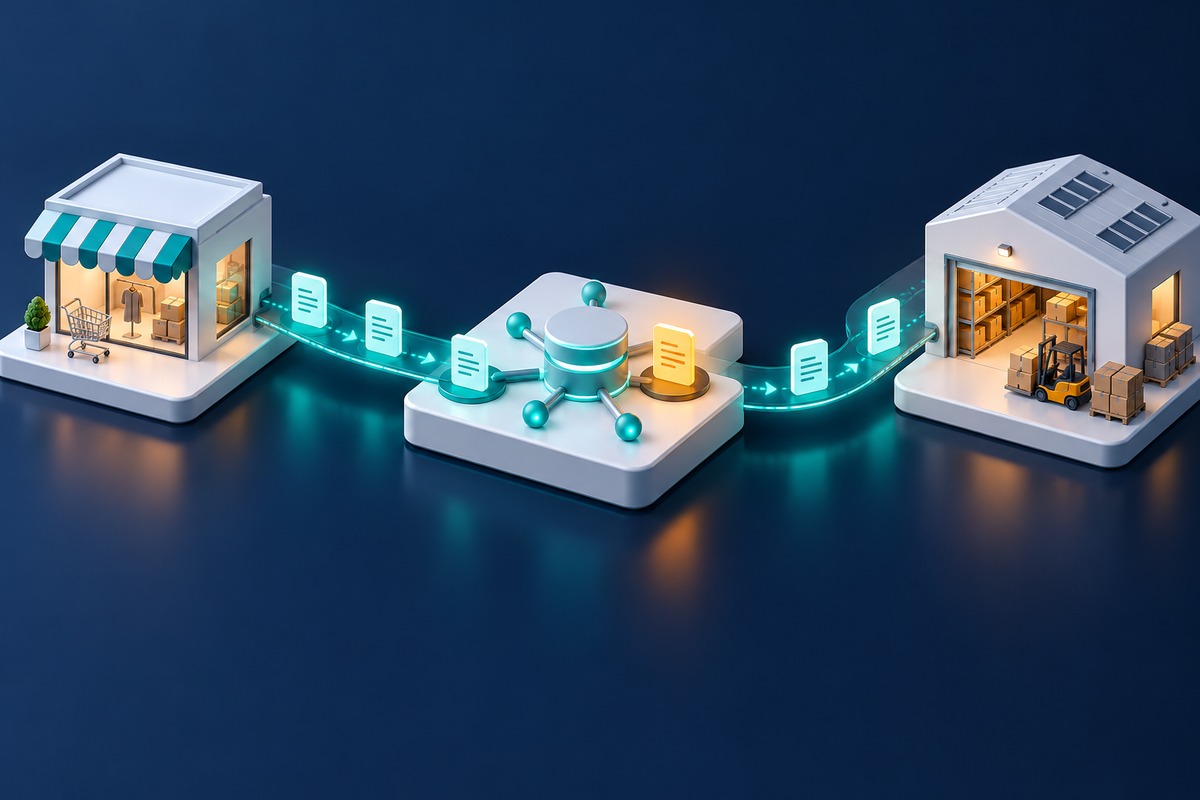
Choose a representative failed order and a comparable successful one. Follow both through the same checkpoints: saved in commerce, captured by the integration, transformed, submitted to the ERP, accepted as a sales order, and released to the next operational step.
At each checkpoint, ask for evidence: the source order ID, integration message ID, ERP reference, timestamp and recorded outcome. A transport acknowledgement proves receipt at that boundary; it may not prove that business validation or downstream processing completed.
Separate symptoms from causes. An order missing from the warehouse may be waiting for an ERP account mapping, held for credit approval, or sitting in an integration queue. Restarting the connector will not resolve every one of those conditions.
For cross-Tasman operations, also confirm the company, currency, warehouse and customer account selected for the transaction. Store timestamps consistently and display the relevant time zone when investigating. Different local dates can make the same event look like two separate incidents.
Classify the failure before choosing a fix
A useful diagnosis separates temporary availability problems, invalid business data, incorrect mappings and stalled background processing. Each needs a different response. Repeating the same request indefinitely can hide the actual issue and increase pressure on an already busy service.
Temporary service or capacity failures
Examples include a connection timeout, a short outage or an API limit being reached. A bounded retry after a suitable delay may succeed. Microsoft’s retry pattern guidance explains why retry behaviour should reflect the fault and avoid overwhelming the destination. Set an escalation point instead of allowing failures to disappear into an endless loop.
Data and business-rule failures
An unknown product code, inactive account, invalid address or unsupported unit of measure needs correction or an explicit business decision. Route the record to an exception list with a useful explanation and a named owner. Retrying unchanged data normally leaves the underlying problem unresolved.
Mapping and processing failures
A connector can run successfully while selecting the wrong warehouse, tax treatment or price group. A background process can also stop while the website remains available. For applicable Adobe Commerce deployments, inspect the relevant consumers and scheduling configuration; Adobe documents how message queue consumers are managed. Confirm the actual deployment architecture before applying that advice.
Recover orders without duplicating business actions
Before replaying a failed order, check whether it already exists in the ERP. A timeout can occur after the destination has saved the record but before the sender receives confirmation. Treating every timeout as a missing order can create duplicates.
Agree a stable identifier for each business operation and retain the relationship between the commerce order, integration record and ERP order. The receiving process should recognise a previously completed operation and return the existing outcome or reject the duplicate safely. Engineers often call this idempotency.
Recovery must also account for what changed after the original attempt. Has the buyer cancelled, has a refund been processed, or has staff already entered the order manually? Replaying an old message without checking current state can revive an action the business no longer wants.
Start with a small, reviewed batch. Verify order totals, payment references, allocations and fulfilment status, then expand recovery while watching for new exceptions. Retain an audit trail showing who approved the replay, which records were processed and the final destination references.
Close the incident only after reconciling the affected population. Compare orders that should have transferred with orders actually created, investigating missing records and duplicates. Payment captured, order accepted and goods dispatched are separate outcomes; checking one does not establish the others.
Treat incorrect prices as a rules problem
When prices differ, compare the same customer, product, quantity, currency, tax basis and effective date in both systems. Check whether the price applies per item, pack or another unit. Screenshots of two unexplained numbers are rarely enough to identify the fault.
Then trace the price rule selected. A contract price may have been replaced by a general price group, an expired agreement may still be cached, or a newly mapped customer may be receiving a default catalogue. Establish which system owns the rule and which system calculates the amount shown at checkout.
Do not fix an integration defect by manually changing prices in several places without recording ownership. That can conceal the mismatch until the next synchronisation overwrites the workaround. Our article on contract pricing, customer price groups and ERP integration explains the underlying decisions.
After correction, verify a representative set of customer agreements and quantities, including an account that should not receive the special price. Have the commercial owner review affected orders rather than allowing a technical replay to decide how existing commitments should be handled.
Find the meaning behind a stock mismatch
Start by asking what each stock number represents. Physical on-hand stock, available-to-sell stock and incoming stock are different concepts. A technically accurate transfer of the wrong value can still create an inaccurate customer promise.
Check reservations, safety stock, warehouse eligibility, pack conversions and the timing of returns. An Australian warehouse and a New Zealand warehouse may have different delivery promises even when they share an ERP. Confirm that stock is offered only through the locations and channels intended to fulfil it.
Next distinguish stale data from an incorrect calculation. Compare the source record’s update time, the last successful transfer and the value applied in commerce. A job marked successful may have processed other products while skipping the SKU that matters.
Repair the underlying rule or failed update before running a broad resynchronisation. Otherwise the same error may be applied across the catalogue. Our inventory accuracy guide covers the wider relationship between the store, warehouse and ERP.
Monitor completed outcomes and the age of the backlog
A useful operational view shows which orders remain unaccepted, how old the oldest pending record is, and which exceptions need intervention. Separate a healthy queue working through normal volume from records that have stopped making progress.
Agree acceptable delays for each business flow. Order transfer before a dispatch cut-off may need different attention from a descriptive product update. Define thresholds from trading requirements and observed behaviour, rather than choosing one universal synchronisation target.
For Shopify integrations, event delivery should be backed by reconciliation. Shopify’s webhook guidance recommends periodically fetching records to keep systems consistent when events are missed or mishandled. It also explains that delivery ordering is not guaranteed. A received event should therefore not be the only evidence that the destination is current.
Send actionable alerts to an accountable team: identify the business flow, affected scope, oldest unresolved record and next step. Keep sensitive customer data out of broad notifications. Routine recovered errors can remain in logs unless their frequency indicates a developing problem.
Decide whether to repair, redesign or replace
Repair is often the appropriate response to a clear mapping defect, expired access or a failed background process when the surrounding integration is maintainable. Confirm the cause and verify the correction against the affected business scenarios.
Consider redesign when failures expose missing controls: no durable record of pending work, no safe replay, no reconciliation or unclear ownership. Replacing a connector without addressing those gaps can recreate the same operating problem with a different interface.
Assess replacement when the existing approach cannot support required business rules, transaction volumes, security or ongoing maintenance. Compare the total transition effort, including mapping, parallel validation, historical references and cutover. A new integration still needs a controlled recovery plan.
Ask prospective partners to demonstrate failure handling alongside the normal order journey. Request a walkthrough of an ERP outage, rejected account, duplicate delivery and manual correction. Clarify responsibility across vendors using our eCommerce support agreement checklist.
Turn the incident into an owned improvement plan
Record the timeline, root cause, affected transactions, customer impact and recovery actions. Assign each follow-up an owner and a completion date. Keep urgent restoration work separate from changes that need design and staging review.
Establish a baseline before claiming improvement: unresolved orders, age of pending work, manual handling time and repeat incidents are useful starting points. Review those measures after the changes under comparable trading conditions. A completed fix is evidence of work delivered; sustained operational improvement needs its own evidence.
If recurring integration issues are consuming your team’s time, talk to OSE about reviewing your commerce and ERP integration. Bring recent failed examples, the systems involved and the operational outcome you need. That gives the review a concrete starting point for deciding what to repair and what to change.
Frequently asked questions
The order may not have reached the integration, may be waiting in a queue, or may have failed ERP validation. It may also exist in the ERP under a different reference or status. Trace the original order through each checkpoint before assuming it needs to be sent again.
No. Temporary availability problems may suit a bounded retry, while invalid data needs correction. Check whether the destination already completed the action and ensure replay cannot create a duplicate order or other unintended business action. Escalate records that remain unresolved.
That depends on the integration design and the business rules required at checkout. Some stores can retain orders for later processing; others depend on live pricing, credit or availability checks. Agree the permitted fallback behaviour in advance and verify it for your actual implementation.
Compare the intended available-to-sell calculation with the value customers see for representative products and locations. Include reservations, returns and units of measure. Review data freshness and reconcile discrepancies; a successful connection alone does not prove that stock promises are correct.
Consider replacement when the current approach cannot meet required rules, capacity, security or maintainability. First establish whether the problem is a repairable defect or a missing operational control. Compare replacement with targeted improvements, including transition risk, validation effort and ongoing support responsibilities.